Abstract
The presence of lens flares in images can significantly reduce the quality of downstream application results for tasks such as 3D scene reconstruction. This is because lens flares are a property of the camera imaging system, and not a part of the underlying scene being modeled. There exist previous methods that tackle removing small flares that are focused around a light source. However, such existing methods cannot handle large flares such as those that take up a full image. In this work, we compile a novel dataset for large flare removal based on both publicly available real-world data, and a procedural generation pipeline. We train a diffusion-based model using our dataset to be able to remove complex and large lens flares.
On the other hand, lens flares remain effective storytelling tools, widely used in the media. While there are ways to simulate 2D flares, representing and reconstructing lens flares consistently in 3D has not yet been explored. To achieve this, we introduce a 3D flare representation model that leverages the symmetric property of lens flares around the principal point of the camera. We propose a computational pipeline for the joint optimization of this flare model alongside a Gaussian splatting model (3DGS). This enables the decomposition of a 3D scene into lens flares and the 3D scene itself, utilizing our flare removal model. Our model enables a view consistent 3D lens flare representation. We perform extensive evaluations to show the effectiveness of both our flare removal and flare representation models.
Method
What are Lens Flares?
Lens flares arise from unintended light paths through a lens when it observes a sufficiently bright light source. We distinguish two subjective categories: scattering flares — glare, shimmer, and streaks from dust and lens defects — and reflective flares, caused by inter-lens reflections in a lens ensemble.
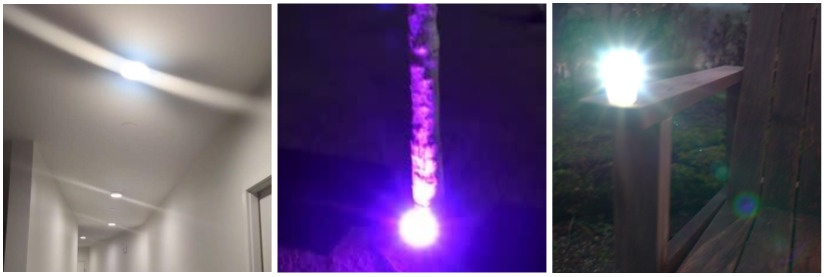
The exact shape of a flare depends jointly on the lens ensemble and the light source — existing stock, procedural, and physically-based simulators can synthesize plausible flares, but none reconstruct the actual pattern present in a given capture. Our goal instead is to reconstruct the flare patterns actually present in footage, preserving lens- and capture-specific characteristics, so they can be removed, reconstructed, and even transferred.
Removal model & training data
We fine-tune a single-step latent diffusion image-to-image model (following Difix3D+) with LoRA adapters — including the VAE encoder, which we found necessary since flare-corrupted images are out of distribution for a pretrained VAE. Supervision includes the light source back in the target image (rather than a post-hoc add-back step), which we show consistently improves results. Fine-tuning takes 20 GPU-hours on a single GPU, versus >4 days for retrained baselines.
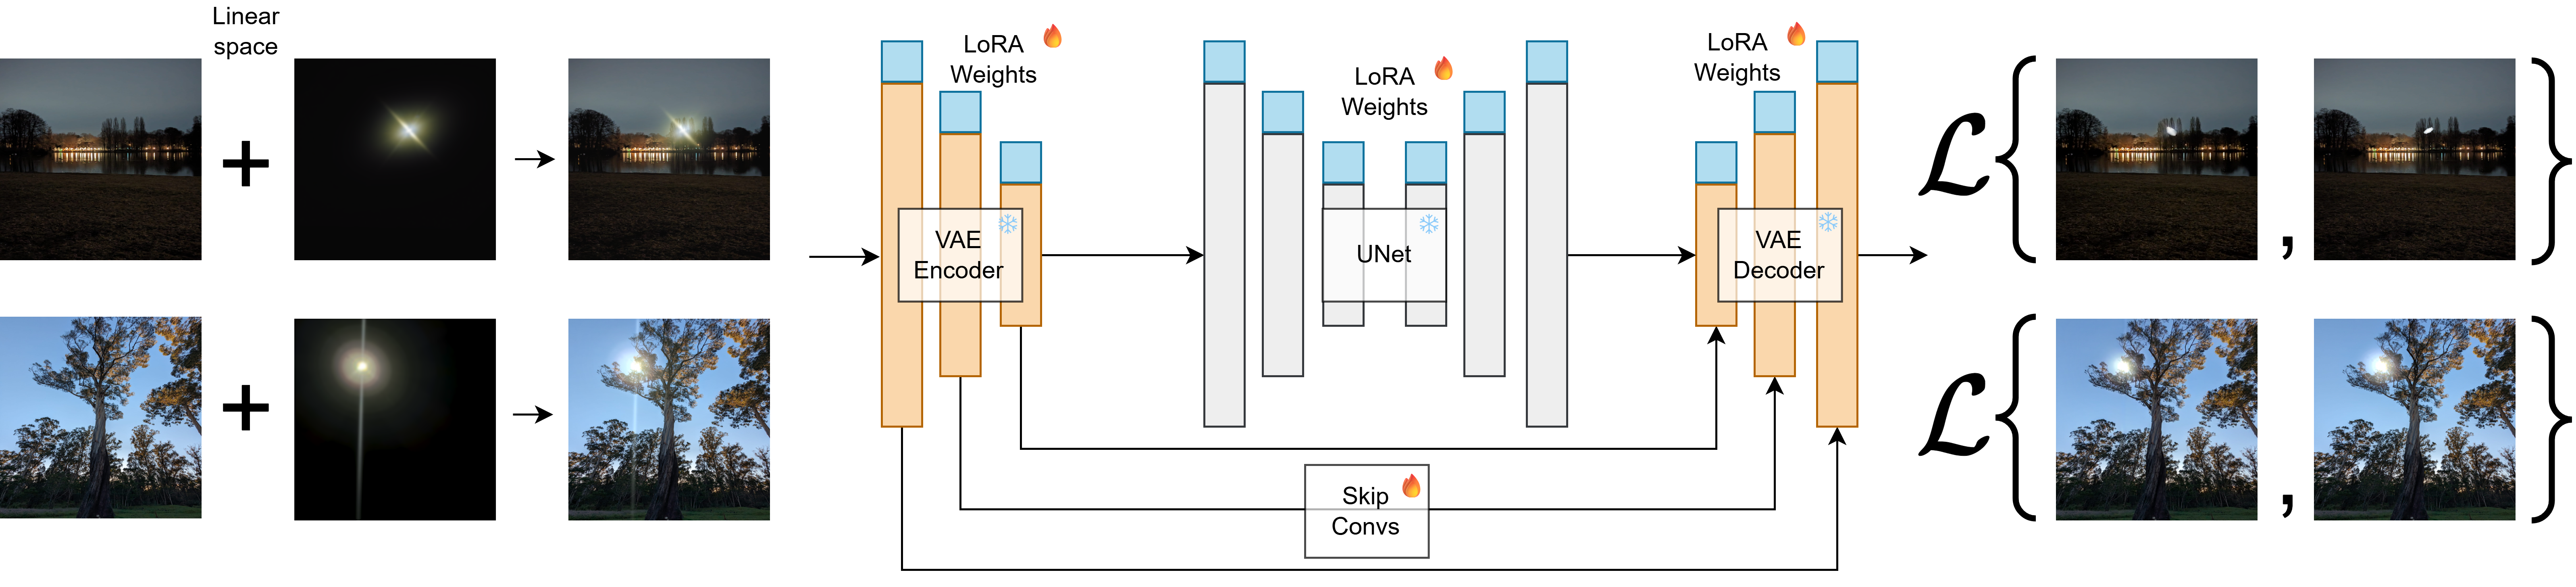
Existing flare datasets are dominated by small scattering flares; full-frame reflective flares are essentially absent. We compile a new dataset from public VFX footage of large reflective flares (1,866 training images from 90 clips, and a 128-image test benchmark built from 18 held-out clips) and augment it with a procedural generator for ring-shaped reflective flares with radially diminishing opacity — a common real-world flare shape that off-the-shelf datasets miss entirely.
Results · Flare Removal
State-of-the-art on scattering & reflective flares
We compare against LightsOut, FR, Flare7K++, ACL-FR, and FlareX — retrained where possible on our combined dataset — on the established Flare7K++ benchmark (scattering flares) and our new VFX benchmark (large reflective flares). Ours‑wGlare / Ours denote our model trained with and without light-source glare in the supervision target.
| Benchmark | Metric | LightsOut | FR | Flare7K++ | ACL-FR | FlareX | Ours‑wGlare | Ours |
|---|---|---|---|---|---|---|---|---|
| Flare7K++ | PSNR ↑ | 16.04 | 24.49 | 26.42 | 24.48 | 25.26 | 26.68 | 25.76 |
| SSIM ↑ | 0.695 | 0.880 | 0.893 | 0.869 | 0.887 | 0.899 | 0.893 | |
| LPIPS ↓ | 0.269 | 0.098 | 0.091 | 0.093 | 0.093 | 0.078 | 0.085 | |
| VFX (ours) | PSNR ↑ | 13.04 | 21.04 | 21.37 | 20.20 | 24.17 | 25.93 | 27.06 |
| SSIM ↑ | 0.336 | 0.927 | 0.919 | 0.886 | 0.938 | 0.937 | 0.941 | |
| LPIPS ↓ | 0.489 | 0.097 | 0.085 | 0.092 | 0.070 | 0.067 | 0.066 |
best best in gold, 2nd second-best in blue. Full ablation columns (w/o light supervision, w/o encoder fine-tuning, w/o VFX data) are in the paper.
| Input | LightsOut | FR | ACL-FR | Flare7K++ | FlareX | Ours‑wGlare | Ours | Ground Truth |
|---|
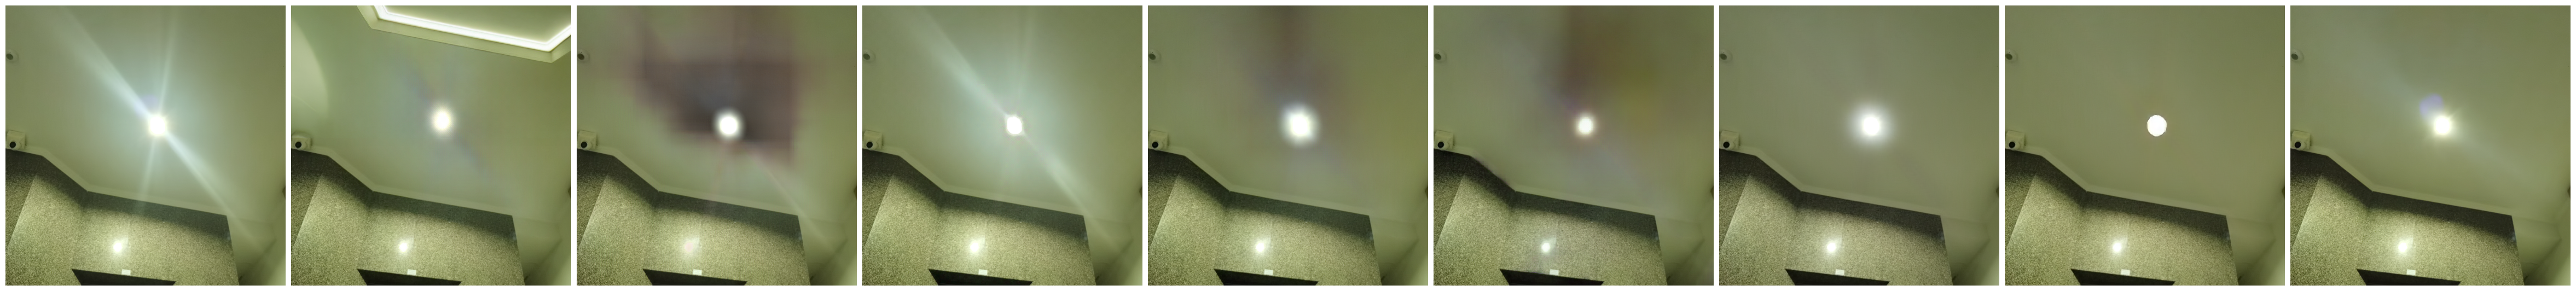
| 19.57 | 21.13 | 22.62 | 25.34 | 21.96 | 30.08 | 27.24 |
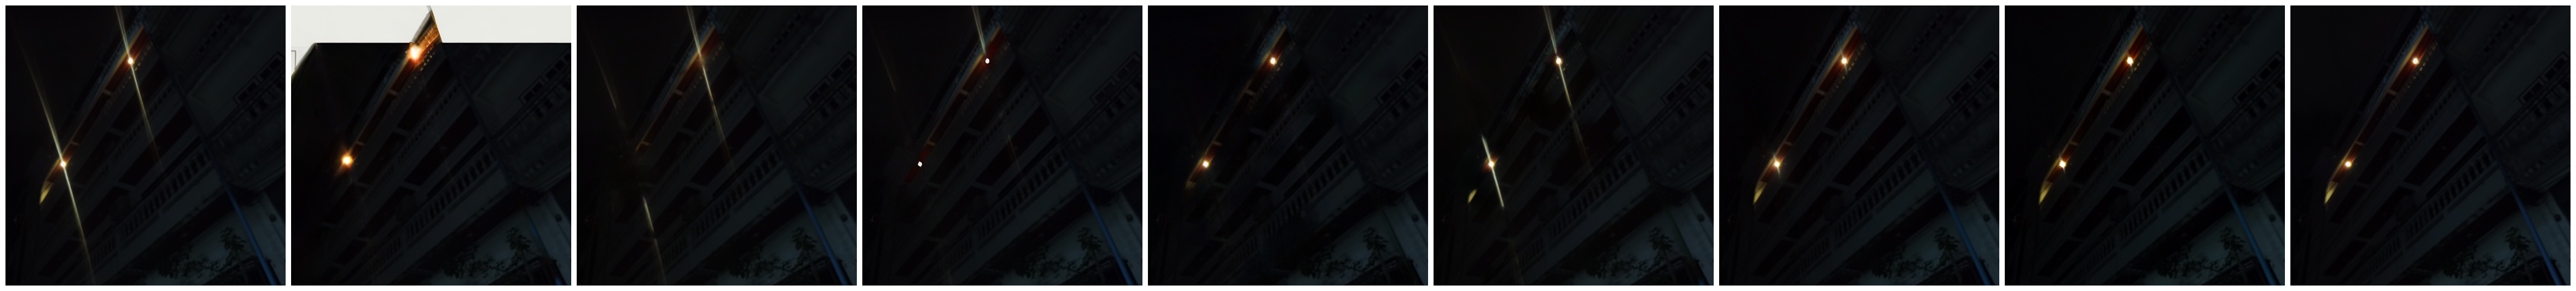
| 9.98 | 29.40 | 31.58 | 33.54 | 29.77 | 38.12 | 38.29 |
| Input | LightsOut | FR | ACL-FR | Flare7K++ | FlareX | Ours‑wGlare | Ours | Ground Truth |
|---|
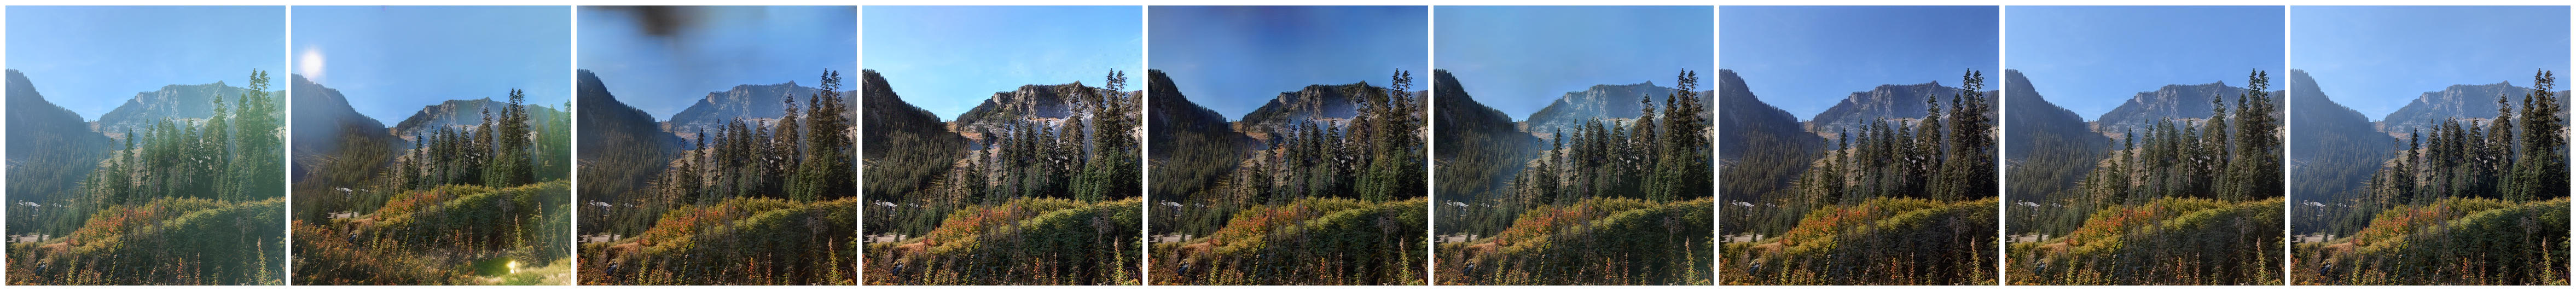
| 15.38 | 18.77 | 18.58 | 15.70 | 20.11 | 20.41 | 25.15 |
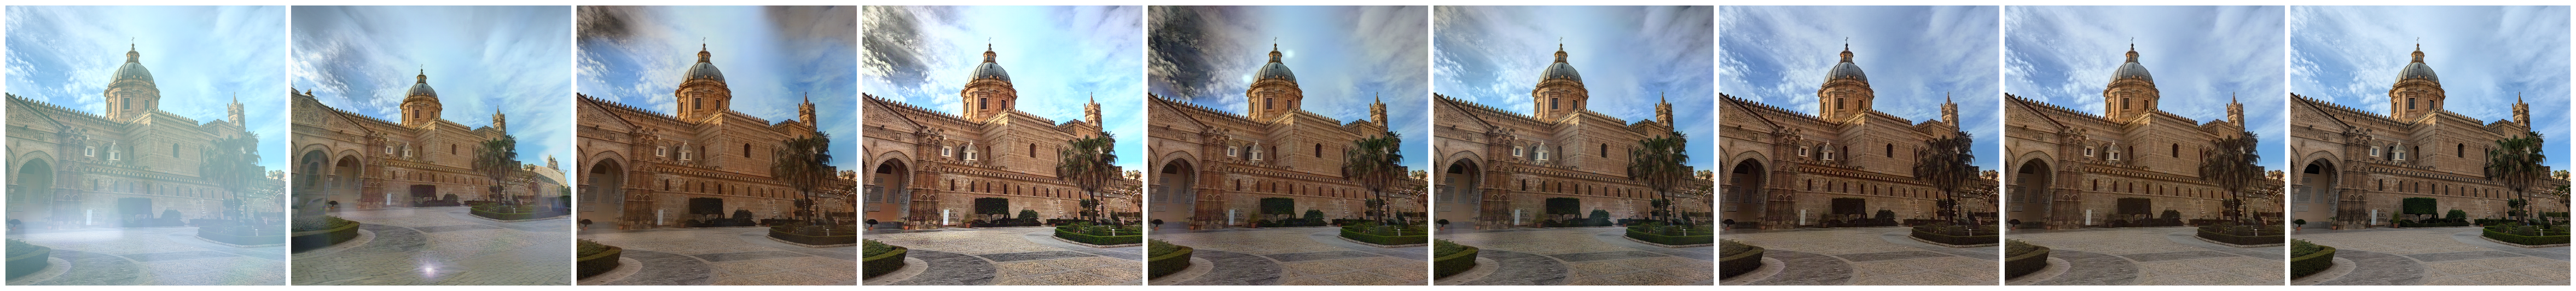
| 13.93 | 18.78 | 17.83 | 16.27 | 22.08 | 22.70 | 27.11 |
Results · Flare-Free 3D Reconstruction
Consistent removal across views improves 3DGS
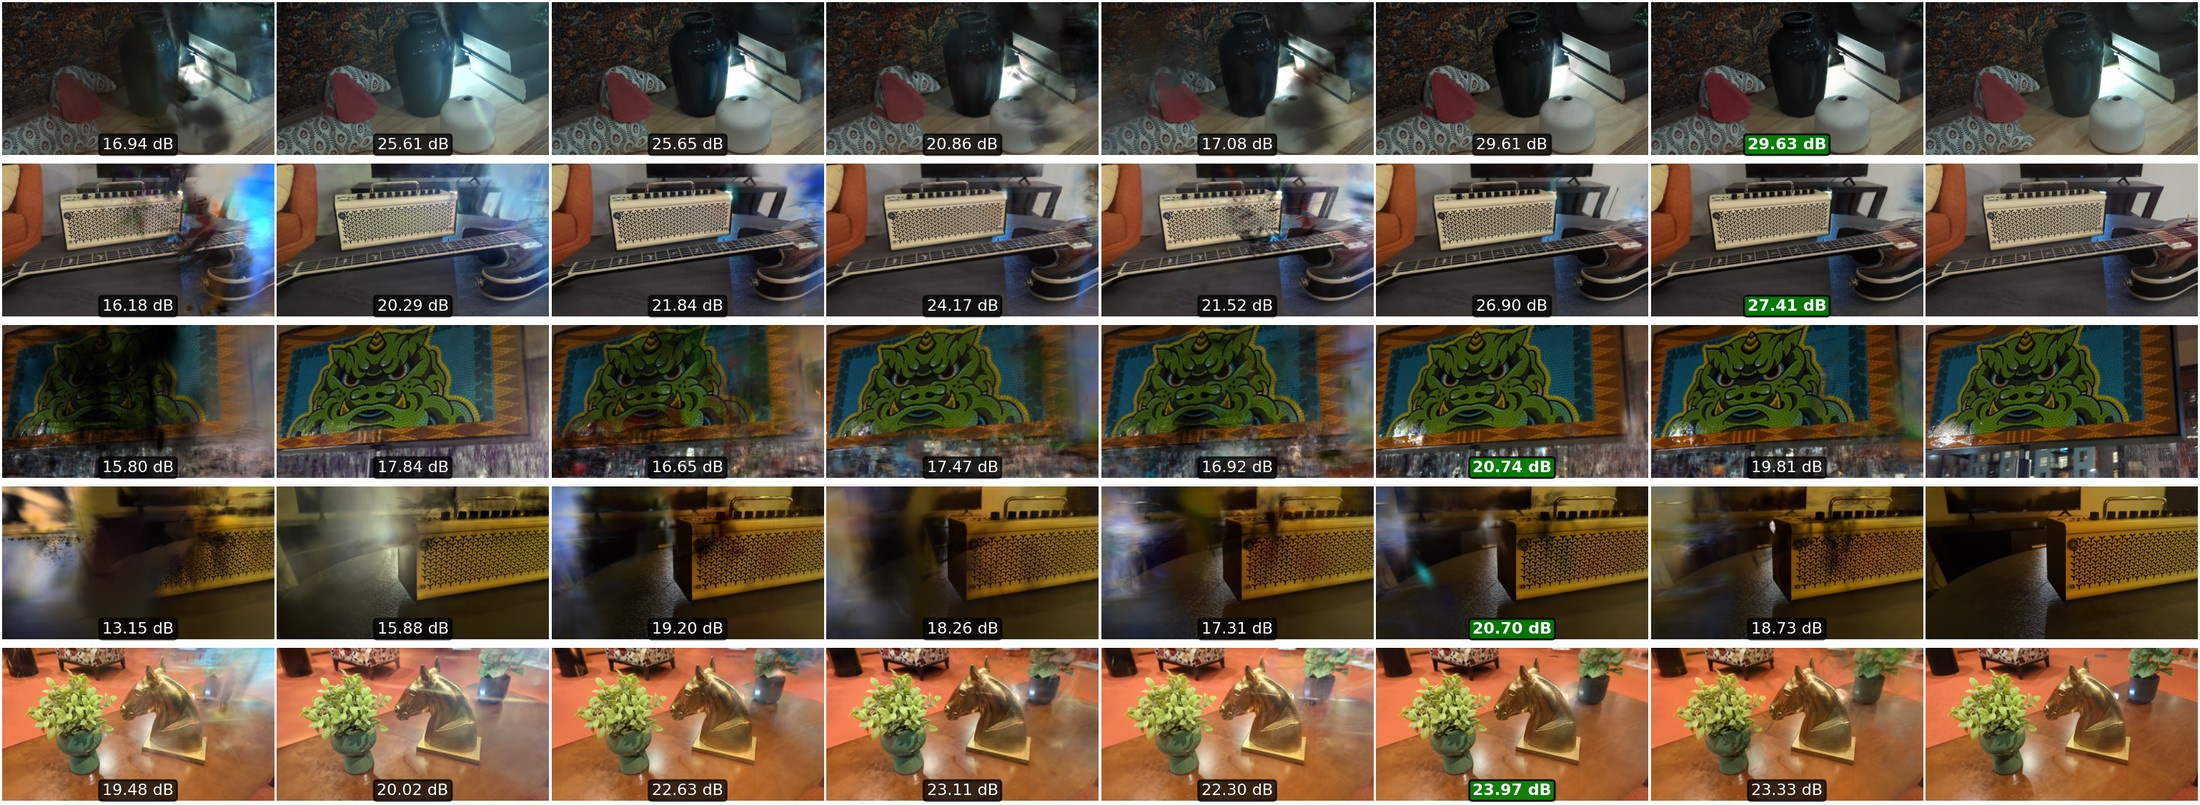
We train 3DGS on flare-corrupted captures, feeding it images pre-processed by each removal baseline, and evaluate on held-out test views that are genuinely flare-free (not model-processed). Inconsistent per-view removal by baselines shows up directly as reconstruction artifacts; our models yield the cleanest geometry.
| Method | PSNR ↑ | SSIM ↑ | LPIPS ↓ |
|---|---|---|---|
| Vanilla 3DGS | 18.68 | 0.741 | 0.318 |
| + BilateralGrid | 18.96 | 0.787 | 0.268 |
| + Flare7K++ | 22.40 | 0.815 | 0.252 |
| + FR | 22.65 | 0.809 | 0.262 |
| + ACL-FR | 21.11 | 0.789 | 0.279 |
| + FlareX | 21.64 | 0.799 | 0.262 |
| + Ours‑wGlare | 23.24 | 0.834 | 0.226 |
| + Ours | 23.93 | 0.837 | 0.220 |
Average over 5 captured multi-view scenes (amp, billboard, dog, guitar, plant), evaluated on flare-free held-out test views.
Method & Results · Representation
Why 3DGS isn't built to handle lens flares
3DGS assumes a static scene observed from multiple viewpoints. Lens flares violate this: they move with the relative motion between camera and light source, so they are fundamentally 3D-inconsistent. Standard and even deformable 3DGS variants end up baking flares into the scene geometry or ignoring them outright.
Our camera-anchored, line-constrained flare representation
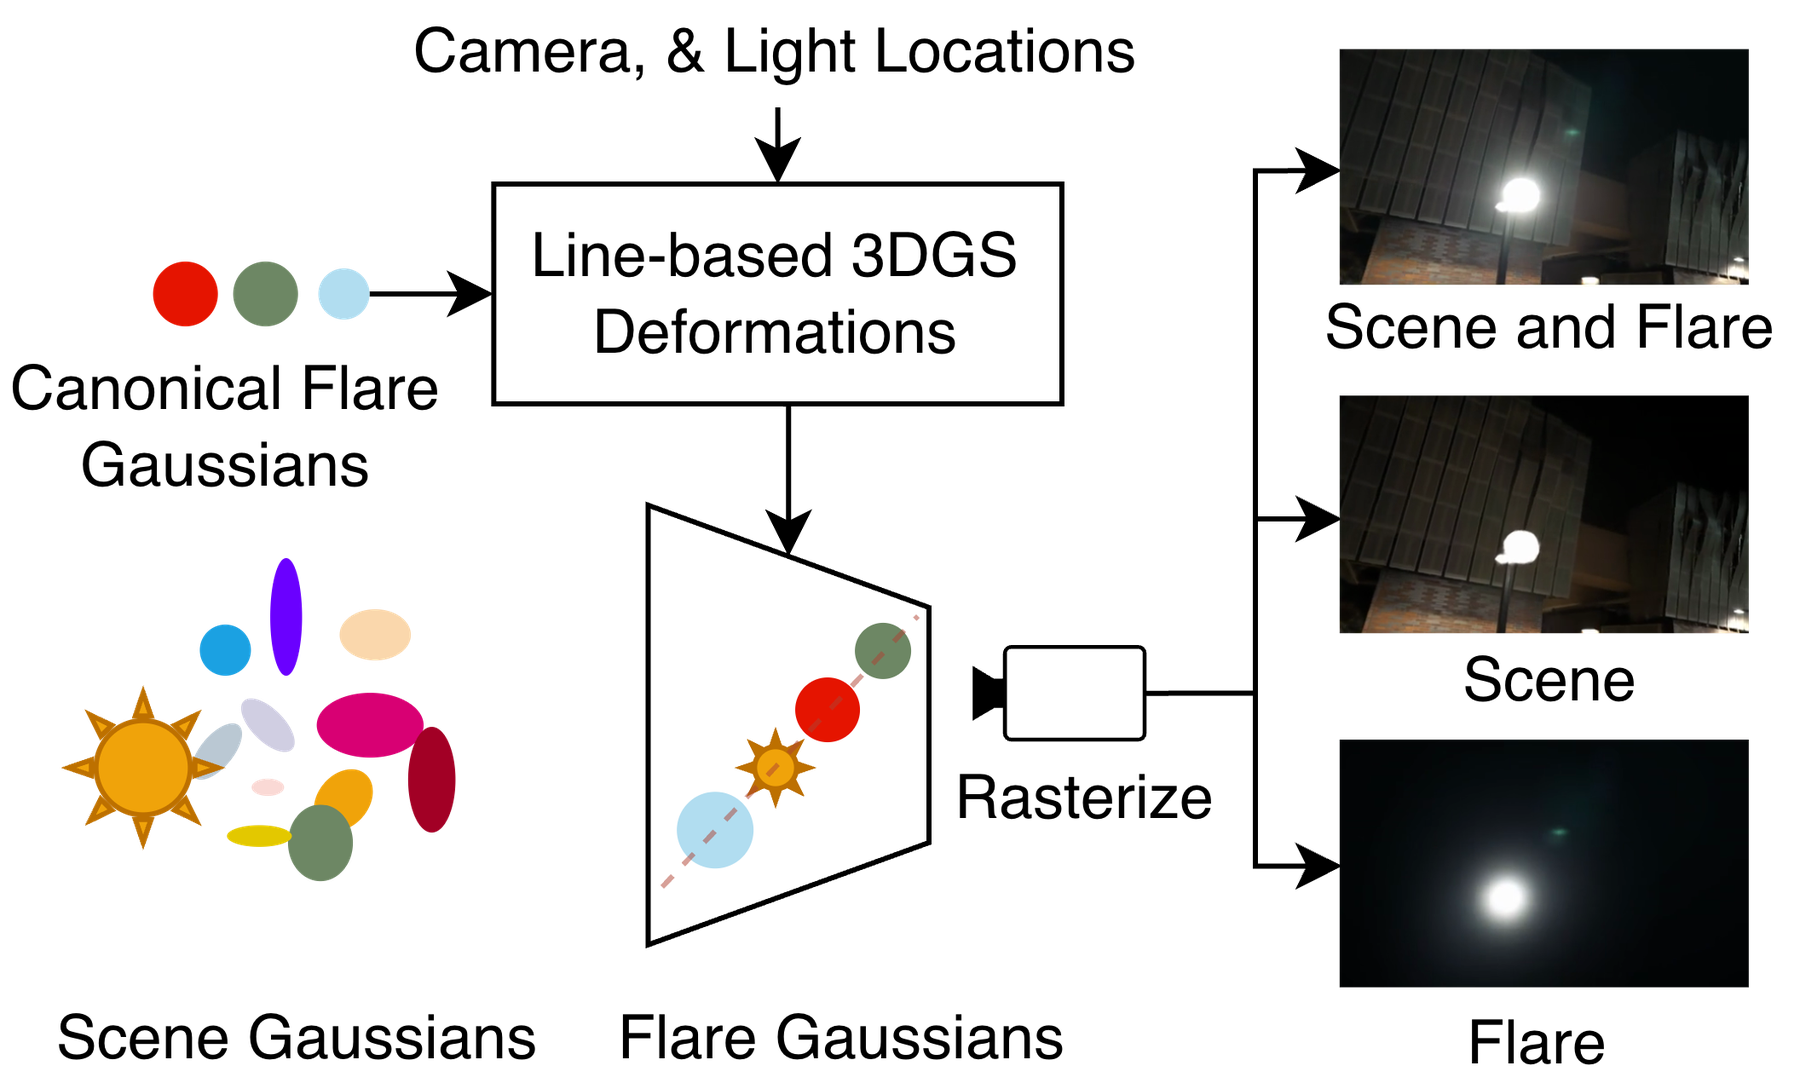
We model each flare as a set of 1D canonical Gaussians constrained to lie on the line through the camera's principal point and the projected light-source location — a well-known geometric property of lens flares. A hash-grid MLP, conditioned on camera and light position, deforms these canonical Gaussians (radial position, scale, opacity, color) per view, plus a small learned 2D offset for off-axis asymmetries. The result is unprojected onto a plane just past the near plane and rasterized together with the scene Gaussians using an unmodified 3DGS rasterizer — so the flare is rigidly tied to the camera, not to scene geometry, and adds negligible rendering overhead.
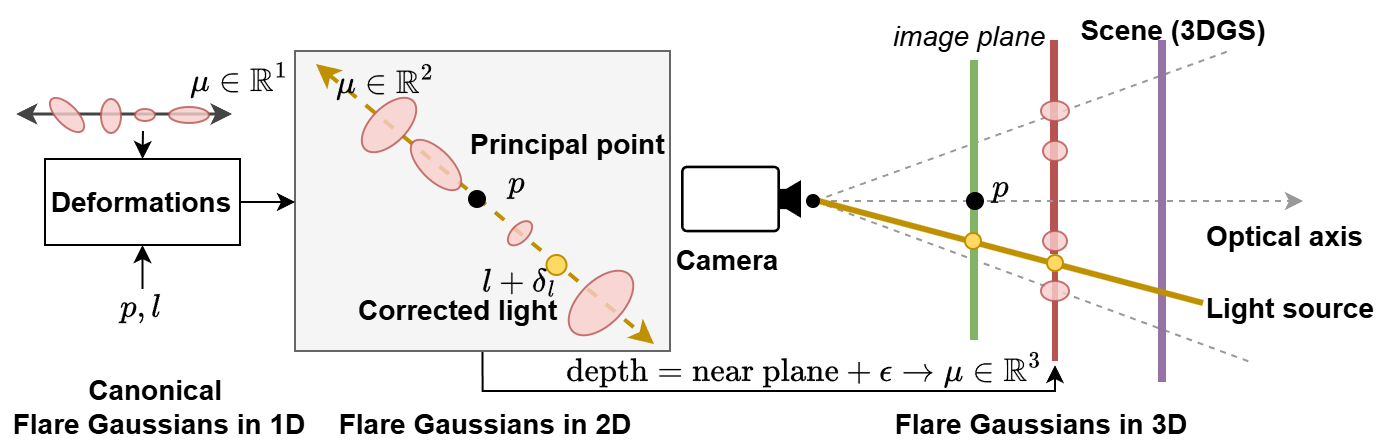
A learned light-position correction (δl) absorbs noise from the upstream light detector (Grounded-SAM2 + 3D clustering), so reconstruction quality is largely decoupled from detection quality — see Robustness below. For scenes with several light sources, we instantiate one flare model per source and merge them, including sources that are off-screen or occluded, as long as their projection has positive depth.
Moving the light along the principal-point line
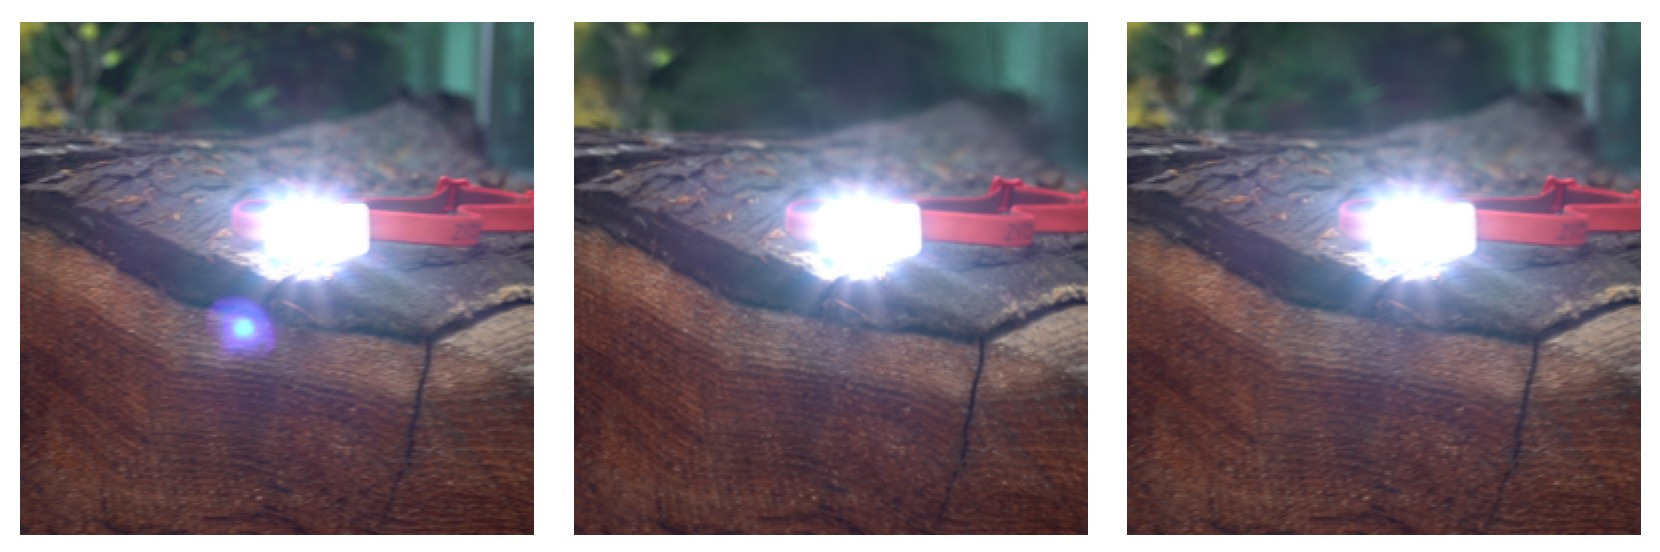
Because our flare model is parameterized on camera and 2D light positions, we can directly control a flare's on-screen position by moving the light-position input, with no retraining. The video below, from the hat sequence, demonstrates our model's performance with the 2D light position changing. To the left we show a control signal where each spoke is a planned motion of the light source, and the red dot marks the light position driving the current render on the right.
In the second video, we additionally change the camera input location to one of the training views, demonstrating how the flare updates consistently as the camera moves too.
Note that our model learns to generalize to these locations just based on 400 training images. This allows us to use the flare model to transfer the flare to another image or scene.
Results · Decomposition
Decomposition videos — all 9 scenes
Each video sweeps all captured cameras for that scene, showing Given, Composite Render, Scene, and Flare, left to right.
Novel-view videos — same 9 scenes
Same decomposition, but along each scene's smooth novel-view trajectory instead of a sweep across all captured cameras. There's no Given column here since novel views were never actually captured.
Results · Ablations
What each design choice buys us
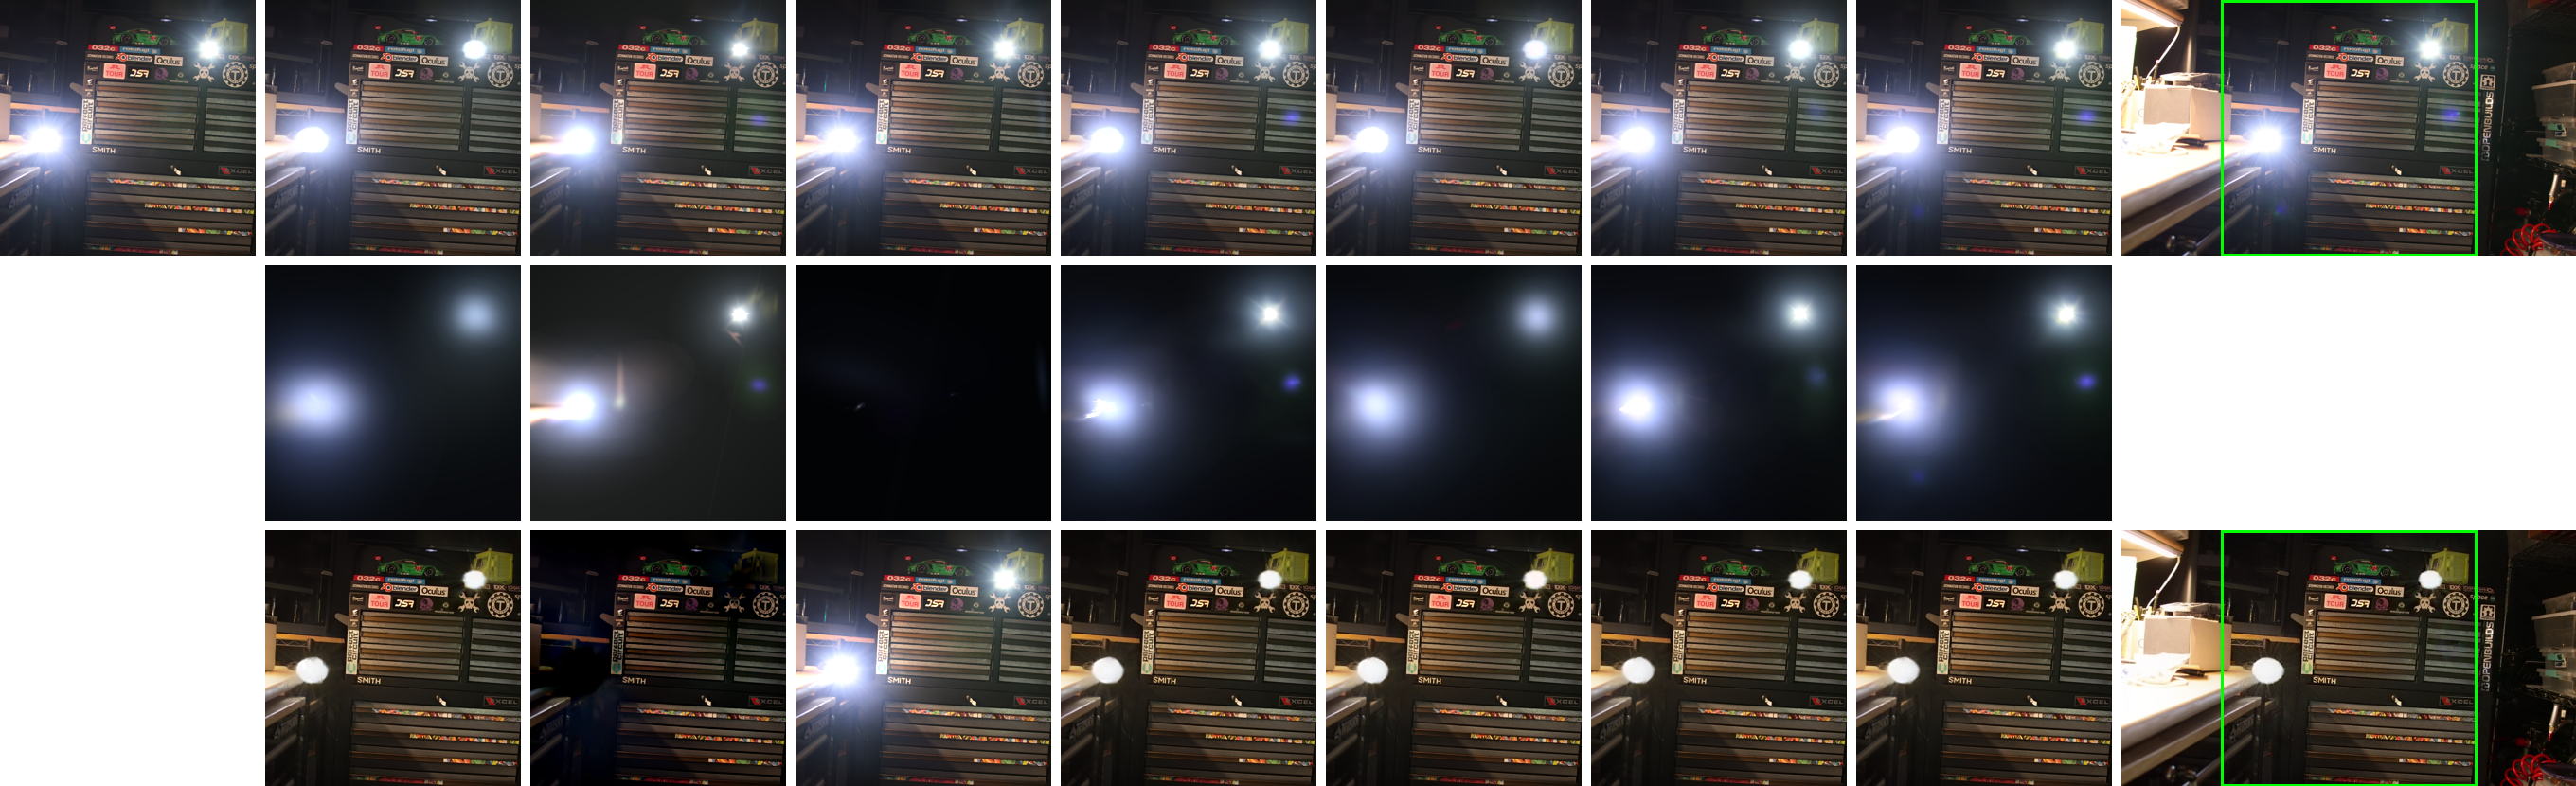
We ablate the flare representation along three axes: the 1D line-constrained parameterization (vs. an unconstrained 2D variant), the scene-supervision strategy (subtracting the reconstructed flare from the input, or no decomposition supervision at all), and the light-position handling (removing the learned correction δl, removing detected light positions and G-SAM2 entirely, or removing the finer off-axis deformation δf).
| 3DGS | 2D‑unconstr. | In‑Flare | Unsup. | w/o δl | w/o G‑SAM2 | w/o δf | Ours | GT |
|---|
| Variant | Flare (Decomposed) | Scene (Decomposed) | Scene + Flare | ||||||
|---|---|---|---|---|---|---|---|---|---|
| PSNR ↑ | SSIM ↑ | LPIPS ↓ | PSNR ↑ | SSIM ↑ | LPIPS ↓ | PSNR ↑ | SSIM ↑ | LPIPS ↓ | |
| Vanilla 3DGS | 32.37 | 0.936 | 0.169 | ||||||
| 2D‑unconstr. | 27.77 | 0.798 | 0.300 | 31.78 | 0.921 | 0.183 | 27.76 | 0.917 | 0.190 |
| In‑Flare | 18.35 | 0.537 | 0.446 | 18.01 | 0.697 | 0.285 | 31.16 | 0.923 | 0.206 |
| Unsup. | 21.79 | 0.542 | 0.385 | 20.97 | 0.813 | 0.262 | 33.67 | 0.939 | 0.166 |
| w/o δl | 33.19 | 0.872 | 0.272 | 31.81 | 0.923 | 0.182 | 33.06 | 0.938 | 0.170 |
| w/o G‑SAM2 | 32.19 | 0.859 | 0.279 | 31.89 | 0.924 | 0.180 | 32.18 | 0.936 | 0.174 |
| w/o δf | 32.99 | 0.872 | 0.263 | 31.76 | 0.922 | 0.183 | 32.90 | 0.937 | 0.170 |
| Ours | 33.27 | 0.874 | 0.270 | 31.79 | 0.922 | 0.182 | 33.06 | 0.937 | 0.168 |
Averaged over all 9 reconstruction scenes. best best in gold, 2nd second-best in blue. Vanilla 3DGS has no scene/flare decomposition, so it's only scored on the composite.
Robustness to noisy light-source detections
|
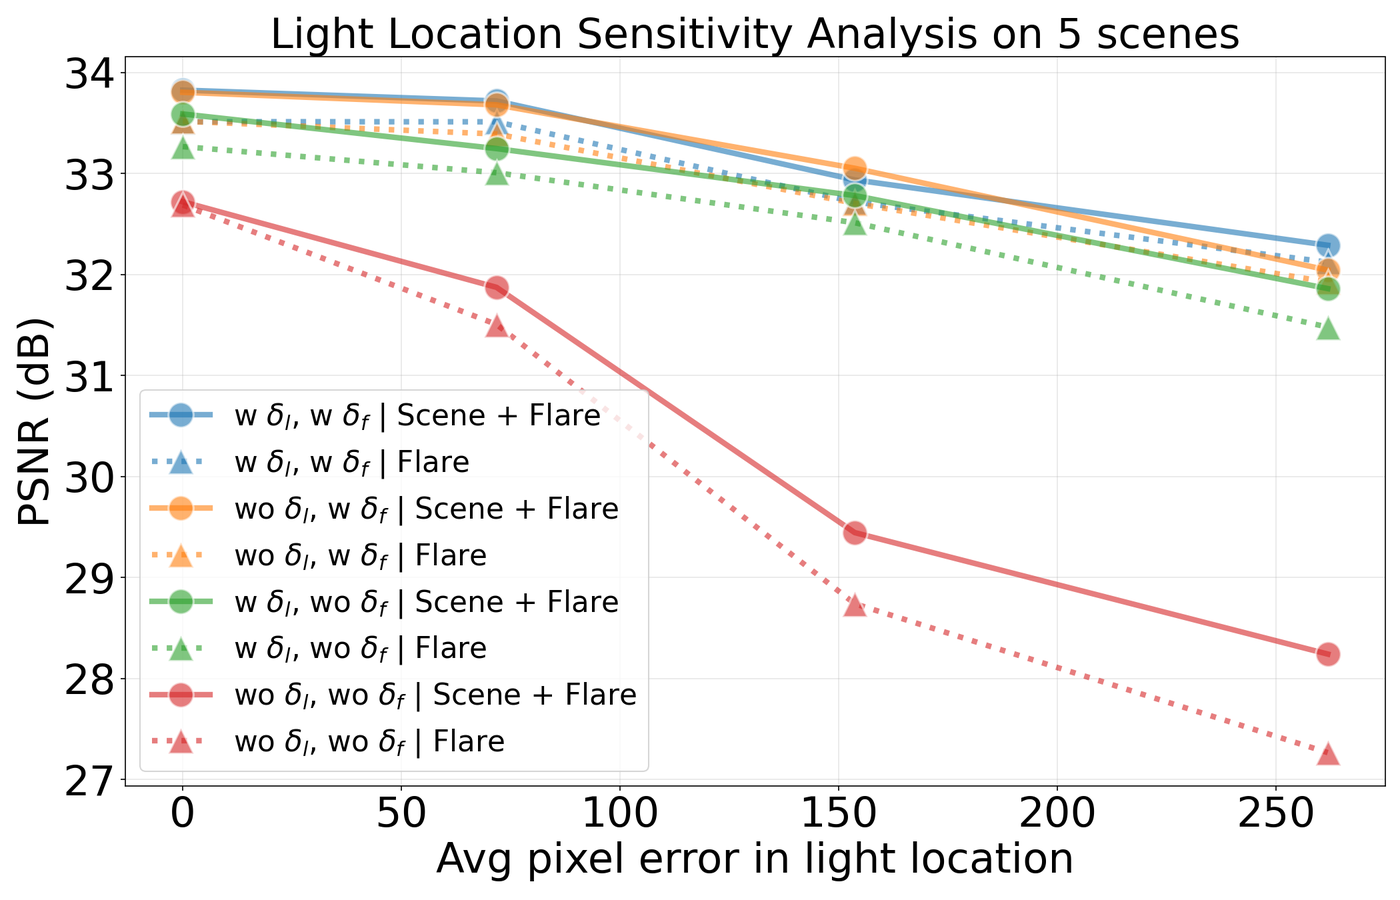
In-the-wild light detection (Grounded-SAM2) can be off by tens to hundreds of pixels under saturation, motion blur, or occlusion. We stress-test by injecting Gaussian noise into the projected light position, up to an average deviation of ∼262 px, across every combination of our light-position correction δl and finer deformations δf. Our full model degrades gracefully: composite PSNR falls only ∼1.5 dB (33.82→32.29 dB) and flare PSNR ∼1.4 dB (33.48→32.12 dB) across the full noise range. Removing either correction alone costs little — at the highest noise level composite PSNR still reaches 32.04 dB without δl and 31.86 dB without δf — but removing both breaks robustness, with composite PSNR falling to 28.24 dB and flare PSNR to 27.27 dB. Combined with the w/o G‑SAM2 ablation above (light positions from a noisy Colmap centroid instead of detection), this shows reconstruction quality is largely decoupled from the upstream light detector. |
|
Application
Flare transfer to new images and new scenes
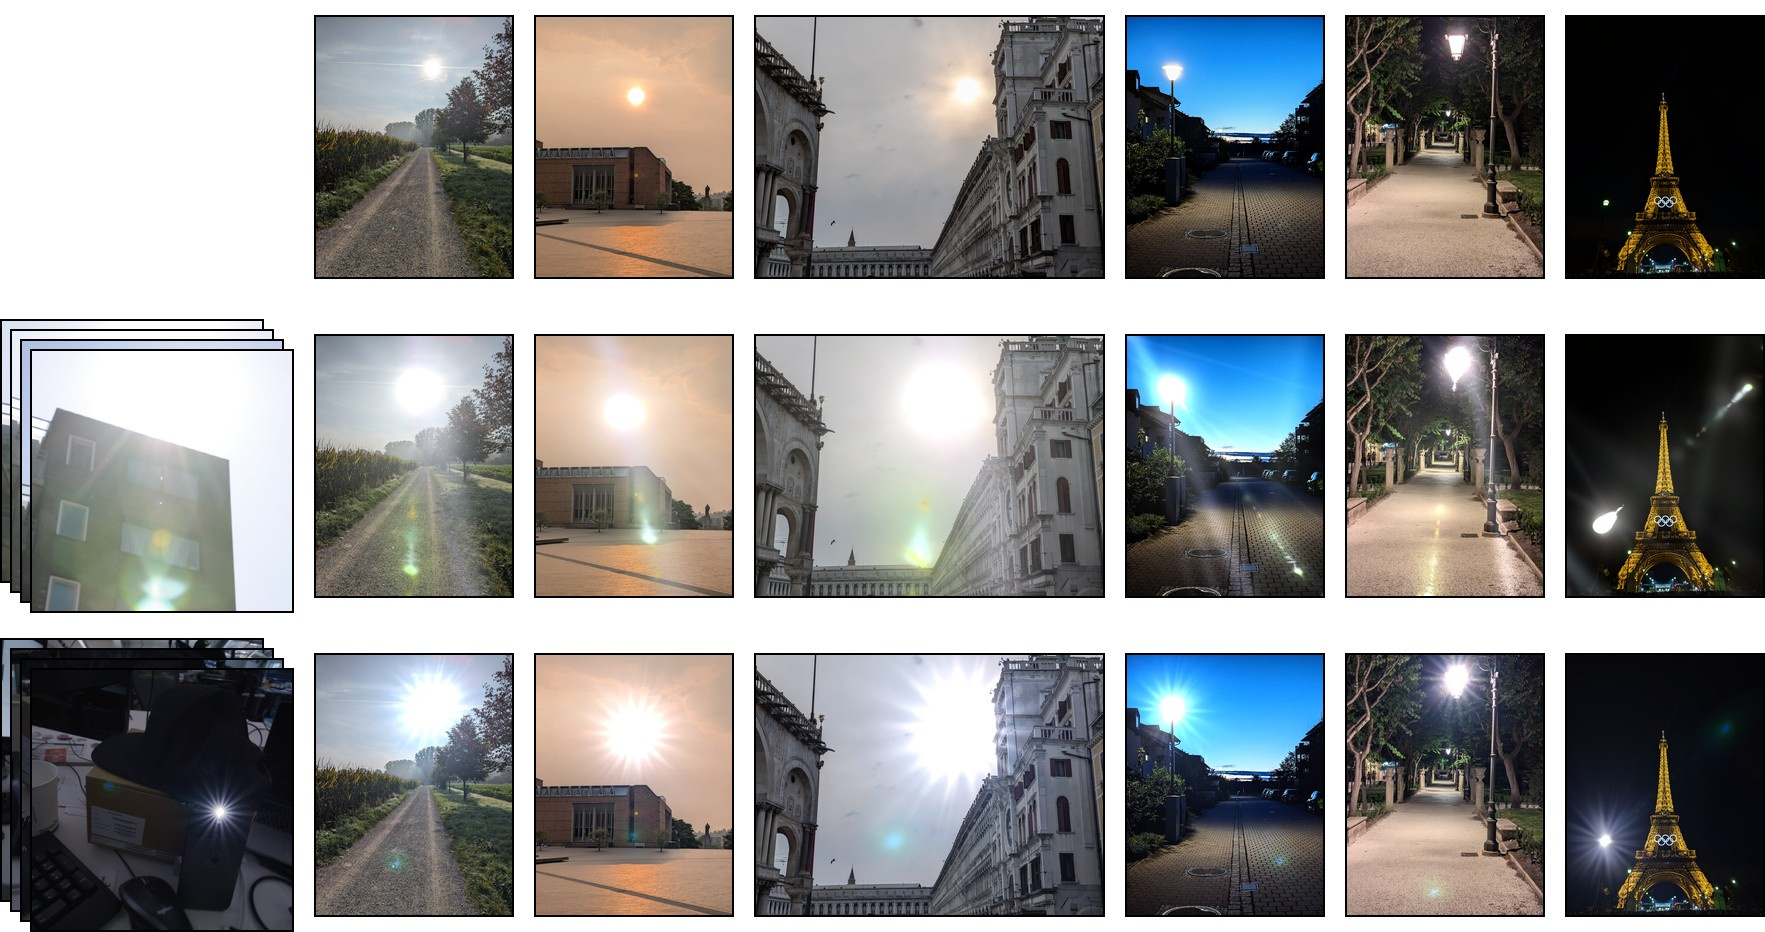
Because flares are represented explicitly and independently of scene geometry, a flare learned from one capture can be transferred elsewhere. For a bare 2D target image with no known camera or geometry, we query the flare MLP with the source camera/light as during training and anchor its placement to a single point in the target image. For a full 3D target scene, we instead re-anchor the transferred flare to the target camera and light position, and run a per-light visibility test against the target scene's depth so the flare is correctly occluded by target geometry.
Limitations & Future Work
What doesn't work yet
- Our flare Gaussians have peak opacity at the mean, decreasing radially outward — a single Gaussian cannot form the annular profile of ring-shaped flares. Our 2D removal model already handles these (via procedural training data), but their 3D representation is left for future work.
- Light sources occluded by scene geometry within a captured view are currently handled only implicitly by the flare model, rather than through an explicit occlusion-aware mechanism.
- The removal model is bounded by the flare types present in our training distribution; flares far outside it are harder to remove convincingly.